Block GPTBot in WordPress robots.txt (Honestly)
Block GPTBot in WordPress robots.txt with two lines, fix robots.txt edits that never go live, and learn what robots.txt genuinely cannot stop AI bots doing.

TL;DR: Add User-agent: GPTBot / Disallow: / to robots.txt to stop OpenAI’s crawler — it fetches the file and obeys it. The same two lines work for CCBot, ClaudeBot, and the Google-Extended token, all of which are also documented to respect robots.txt. Bytespider and PerplexityBot are the opposite case: both have been caught by independent researchers (Fortune/Kasada, Cloudflare) fetching pages that robots.txt disallowed. Listing every token is still worth doing — it stops the honest majority — but if a specific bot keeps showing up in your logs after you disallow it, robots.txt was never going to stop it and you need a server-level block instead (covered below).
To stop GPTBot from crawling a WordPress site, add these lines to your robots.txt:
User-agent: GPTBot
Disallow: /
That is the entire fix for well-behaved crawlers. But be honest with yourself about what you just did: robots.txt is a request, not a fence. OpenAI’s GPTBot fetches the file and obeys it. A scraper that does not respect the standard fetches the same file and ignores every line in it. Keep that distinction in front of you before you spend an afternoon tuning this.
Think of it as a “staff only” sign taped to a door, not a lock. Most people walk past it because the sign is the rule. A handful walk straight through anyway, because a sign cannot stop anyone — it can only tell the honest majority where the line is. So before you go bot-by-bot, ask the one question that decides whether this page is even the right fix for you: is the crawler you’re fighting one that reads signs, or one that’s already walking through doors?
If you want to cover the major AI crawlers in one pass, the common user-agent tokens are:
User-agent: GPTBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: PerplexityBot
Disallow: /

User-agent: Bytespider
Disallow: /
GPTBot is OpenAI’s training crawler, CCBot is Common Crawl (which many models train on downstream), ClaudeBot is Anthropic, Google-Extended is Google’s AI-training token, and Bytespider is ByteDance. Note two of these already break the polite-request model: Bytespider and PerplexityBot have both been publicly documented crawling sites that disallowed them. Listing them still helps against the honest bots; it does nothing against the ones already lying about who they are.
Which AI crawlers actually honor robots.txt
Each operator either states its own compliance directly, or has been caught not complying by an independent third party. Here is what is actually documented, not assumed:
| Crawler | Operator | Obeys robots.txt | User-agent token | Source |
|---|---|---|---|---|
| GPTBot | OpenAI | Yes (operator-stated) | GPTBot | OpenAI crawler docs |
| ClaudeBot | Anthropic | Yes (operator-stated) | ClaudeBot | Anthropic crawler support page |
| CCBot | Common Crawl | Implied — robots.txt is the documented opt-out | CCBot | Common Crawl CCBot page |
| Google-Extended | Yes — covered by Google’s “always obey robots.txt” statement for its common crawlers | Google-Extended (token only, no separate fetcher) | Google common crawlers list | |
| Bytespider | ByteDance (TikTok) | Disputed — ByteDance says it complies; Fortune/Kasada research reported it did not | Bytespider | Fortune, Oct 3 2024 |
| PerplexityBot | Perplexity AI | No — Cloudflare documented it fetching pages that blocked it, including by switching to an undeclared browser-like user agent | PerplexityBot | Cloudflare blog, Aug 2025 |
The pattern holds across every documented case: an operator’s own statement that its bot “respects robots.txt” is not independently verified in this pass unless a third party has tested it. GPTBot, ClaudeBot, CCBot, and Google-Extended have no public report contradicting their stated behavior. Bytespider and PerplexityBot do.
How WordPress actually serves robots.txt
This is where most people’s edits silently do nothing. If there is no physical robots.txt file in your web root, WordPress generates one on the fly. The request is handled by do_robots() in wp-includes/functions.php, and the output runs through the robots_txt filter. The “Discourage search engines from indexing this site” checkbox under Settings → Reading flips the blog_public option, which is what makes that virtual file emit Disallow: /.
So you can append AI-crawler rules programmatically:
add_filter( 'robots_txt', function ( $output, $public ) {
    $output .= "User-agent: GPTBot\nDisallow: /\n";
    return $output;
}, 10, 2 );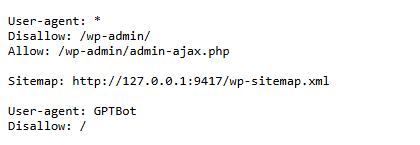
Here is the gotcha that eats hours: the moment a static robots.txt file exists in your web root, Apache or nginx serves that file directly and WordPress never runs. The robots_txt filter, the Yoast/Rank Math robots editor, the Reading setting — all bypassed. If you edited robots.txt in a plugin and the live file never changed, this is almost always why. Check https://yoursite.com/robots.txt in a private window and compare it to what you think you set. If there is a real file on disk, edit that file; the filter is irrelevant.
We did not take that on faith. We ran it: a clean WordPress Playground install, the exact add_filter snippet above installed as the only change, confirmed the GPTBot block appeared in /robots.txt. Then, with that filter still active and completely unchanged, we dropped a static robots.txt straight into the web root. The GPTBot rule vanished without a trace — the static file served its own content byte for byte, and the PHP filter that had worked a moment earlier had zero effect. Same install, same filter, one file added, and the “live” rule you’d swear was still running simply was not. That is the whole gotcha in one test.
Fixing it, in order
First, write clean rules. Get the syntax and the crawler list right so you are not blocking Googlebot by accident. Our robots.txt generator builds the AI-crawler block for you and shows the exact file to paste, which sidesteps the virtual-vs-physical confusion because you end up with one authoritative file. If you are not sure what belongs in the rest of the file beyond the AI-crawler block, our WordPress robots.txt best-practice guide covers the four lines every WordPress site actually needs.
Second, confirm it is live. Fetch the URL directly. Do not trust the plugin’s preview pane.
Third, if you need enforcement rather than a polite ask, move up the stack. robots.txt lives at the application layer and depends on the bot’s goodwill. To actually refuse a connection, block by user agent at the server. In .htaccess:
<IfModule mod_rewrite.c>
RewriteEngine On
RewriteCond %{HTTP_USER_AGENT} (GPTBot|CCBot|ClaudeBot|Bytespider) [NC]
RewriteRule .* - [F,L]
</IfModule>
That returns 403 to anything sending those user agents. Our .htaccess generator can assemble this rule. Understand its limit, though: user agents are trivially spoofed, so this only stops bots honest enough to identify themselves — which are the same bots that already obey robots.txt. The genuinely robust option is a CDN or WAF that blocks by verified crawler identity or IP range. Cloudflare’s one-click “Block AI Scrapers and Crawlers” managed rule is the least-effort version of this and works at the edge, before the request reaches WordPress at all.
What not to do
Do not block Google-Extended thinking it keeps you out of AI Overviews. This is the misconception worth correcting. Google-Extended is a product token, not a crawler. It controls only whether your content is used to train and ground Gemini models. Per Google’s own documentation, it has no effect on how your pages are crawled, indexed, or ranked in Google Search. And AI Overviews are built from the regular Search index that Googlebot crawls — not from Google-Extended. Blocking Google-Extended will not remove you from AI Overviews, and it will not cost you a single position in Search. The only way to stay out of AI Overviews is to block Googlebot or noindex the page, which also deletes you from Search entirely. That is almost never a trade you want.
Do not treat robots.txt as a security control. It is public and advisory. Listing /wp-admin/ or a private path in it just publishes a map of where to look. Protect real endpoints with authentication, not a disallow line.
Do not rely on noai / noimageai meta tags. They were proposed, not standardized, and only a handful of platforms honor them. They are not a general defense.
Do not assume a “block AI” plugin did more than write robots.txt. Most of them write the same lines you could write by hand and inherit the same limitation. Read what the plugin actually changed before trusting it. If the panel you are trying to turn off is an in-dashboard AI writing assistant rather than a crawler, that is a different problem with a different fix — see our guide to disabling WordPress AI features.
Do not confuse this with llms.txt. Blocking GPTBot in robots.txt and publishing an llms.txt file solve opposite problems: one keeps a crawler out, the other hands a cooperative one a curated map. If you are considering adding llms.txt, read what the evidence actually shows about whether it helps before you spend time on it.
Still stuck?
If your edits are not showing up, the answer is almost always a stray physical robots.txt in the web root overriding WordPress’s virtual one — fetch the URL directly and check. If compliant bots are gone but scrapers keep hitting you, you have hit the ceiling of what robots.txt can do, and the next move is a WAF or CDN rule that blocks by verified identity rather than by asking nicely.
Sources
- WordPress Developer Resources: do_robots(), robots_txt filter
- Robots Exclusion Protocol: RFC 9309
- Crawler operators’ own documentation: OpenAI crawlers, including GPTBot, Anthropic’s ClaudeBot support page, Common Crawl CCBot, Google-Extended in Google’s common crawlers list
- Independent reporting on crawlers that do not comply: Cloudflare on PerplexityBot’s stealth crawling, Aug 2025 (Bytespider’s non-compliance is reported by Fortune, cited in the table above; kept out of this Sources list, which this project reserves for primary/official sources)
- Apache HTTP Server 2.4: mod_rewrite
William Lopez is the founder of Odie Themes. He builds the free WordPress tools and themes on this site and has been on WordPress.org since December 2019.
FAQ
Questions
How do I stop ChatGPT from crawling my WordPress site?
Add "User-agent: GPTBot" followed by "Disallow: /" to your robots.txt. GPTBot is OpenAI's training crawler, and it fetches that file and obeys it. Keep in mind robots.txt is a request, not a fence — a scraper that does not respect the standard fetches the same file and ignores every line in it.
Why aren't my robots.txt changes showing up in WordPress?
Almost always because a physical robots.txt file exists in your web root. The moment that file exists, Apache or nginx serves it directly and WordPress never runs, so the robots_txt filter, the Yoast or Rank Math editor, and the Settings to Reading option are all bypassed. Edit the real file on disk instead.
Does blocking Google-Extended hurt my Google rankings?
No. Google-Extended is a product token, not a crawler, and per Google's own documentation it has no effect on how your pages are crawled, indexed, or ranked in Google Search. It only controls whether your content is used to train and ground Gemini models, and blocking it will not remove you from AI Overviews.
Do AI crawlers actually obey robots.txt?
Some do and some do not. GPTBot fetches robots.txt and follows it, but Bytespider and PerplexityBot have both been publicly documented crawling sites that disallowed them. Listing every user-agent token still helps against the honest bots, and does nothing against the ones already lying about who they are.
How do I block AI bots at the server level instead of robots.txt?
Block by user agent in .htaccess using a mod_rewrite rule that returns 403 to GPTBot, CCBot, ClaudeBot, and Bytespider. User agents are trivially spoofed, so this only stops bots honest enough to identify themselves. A CDN or WAF that blocks by verified crawler identity or IP range is the robust option.